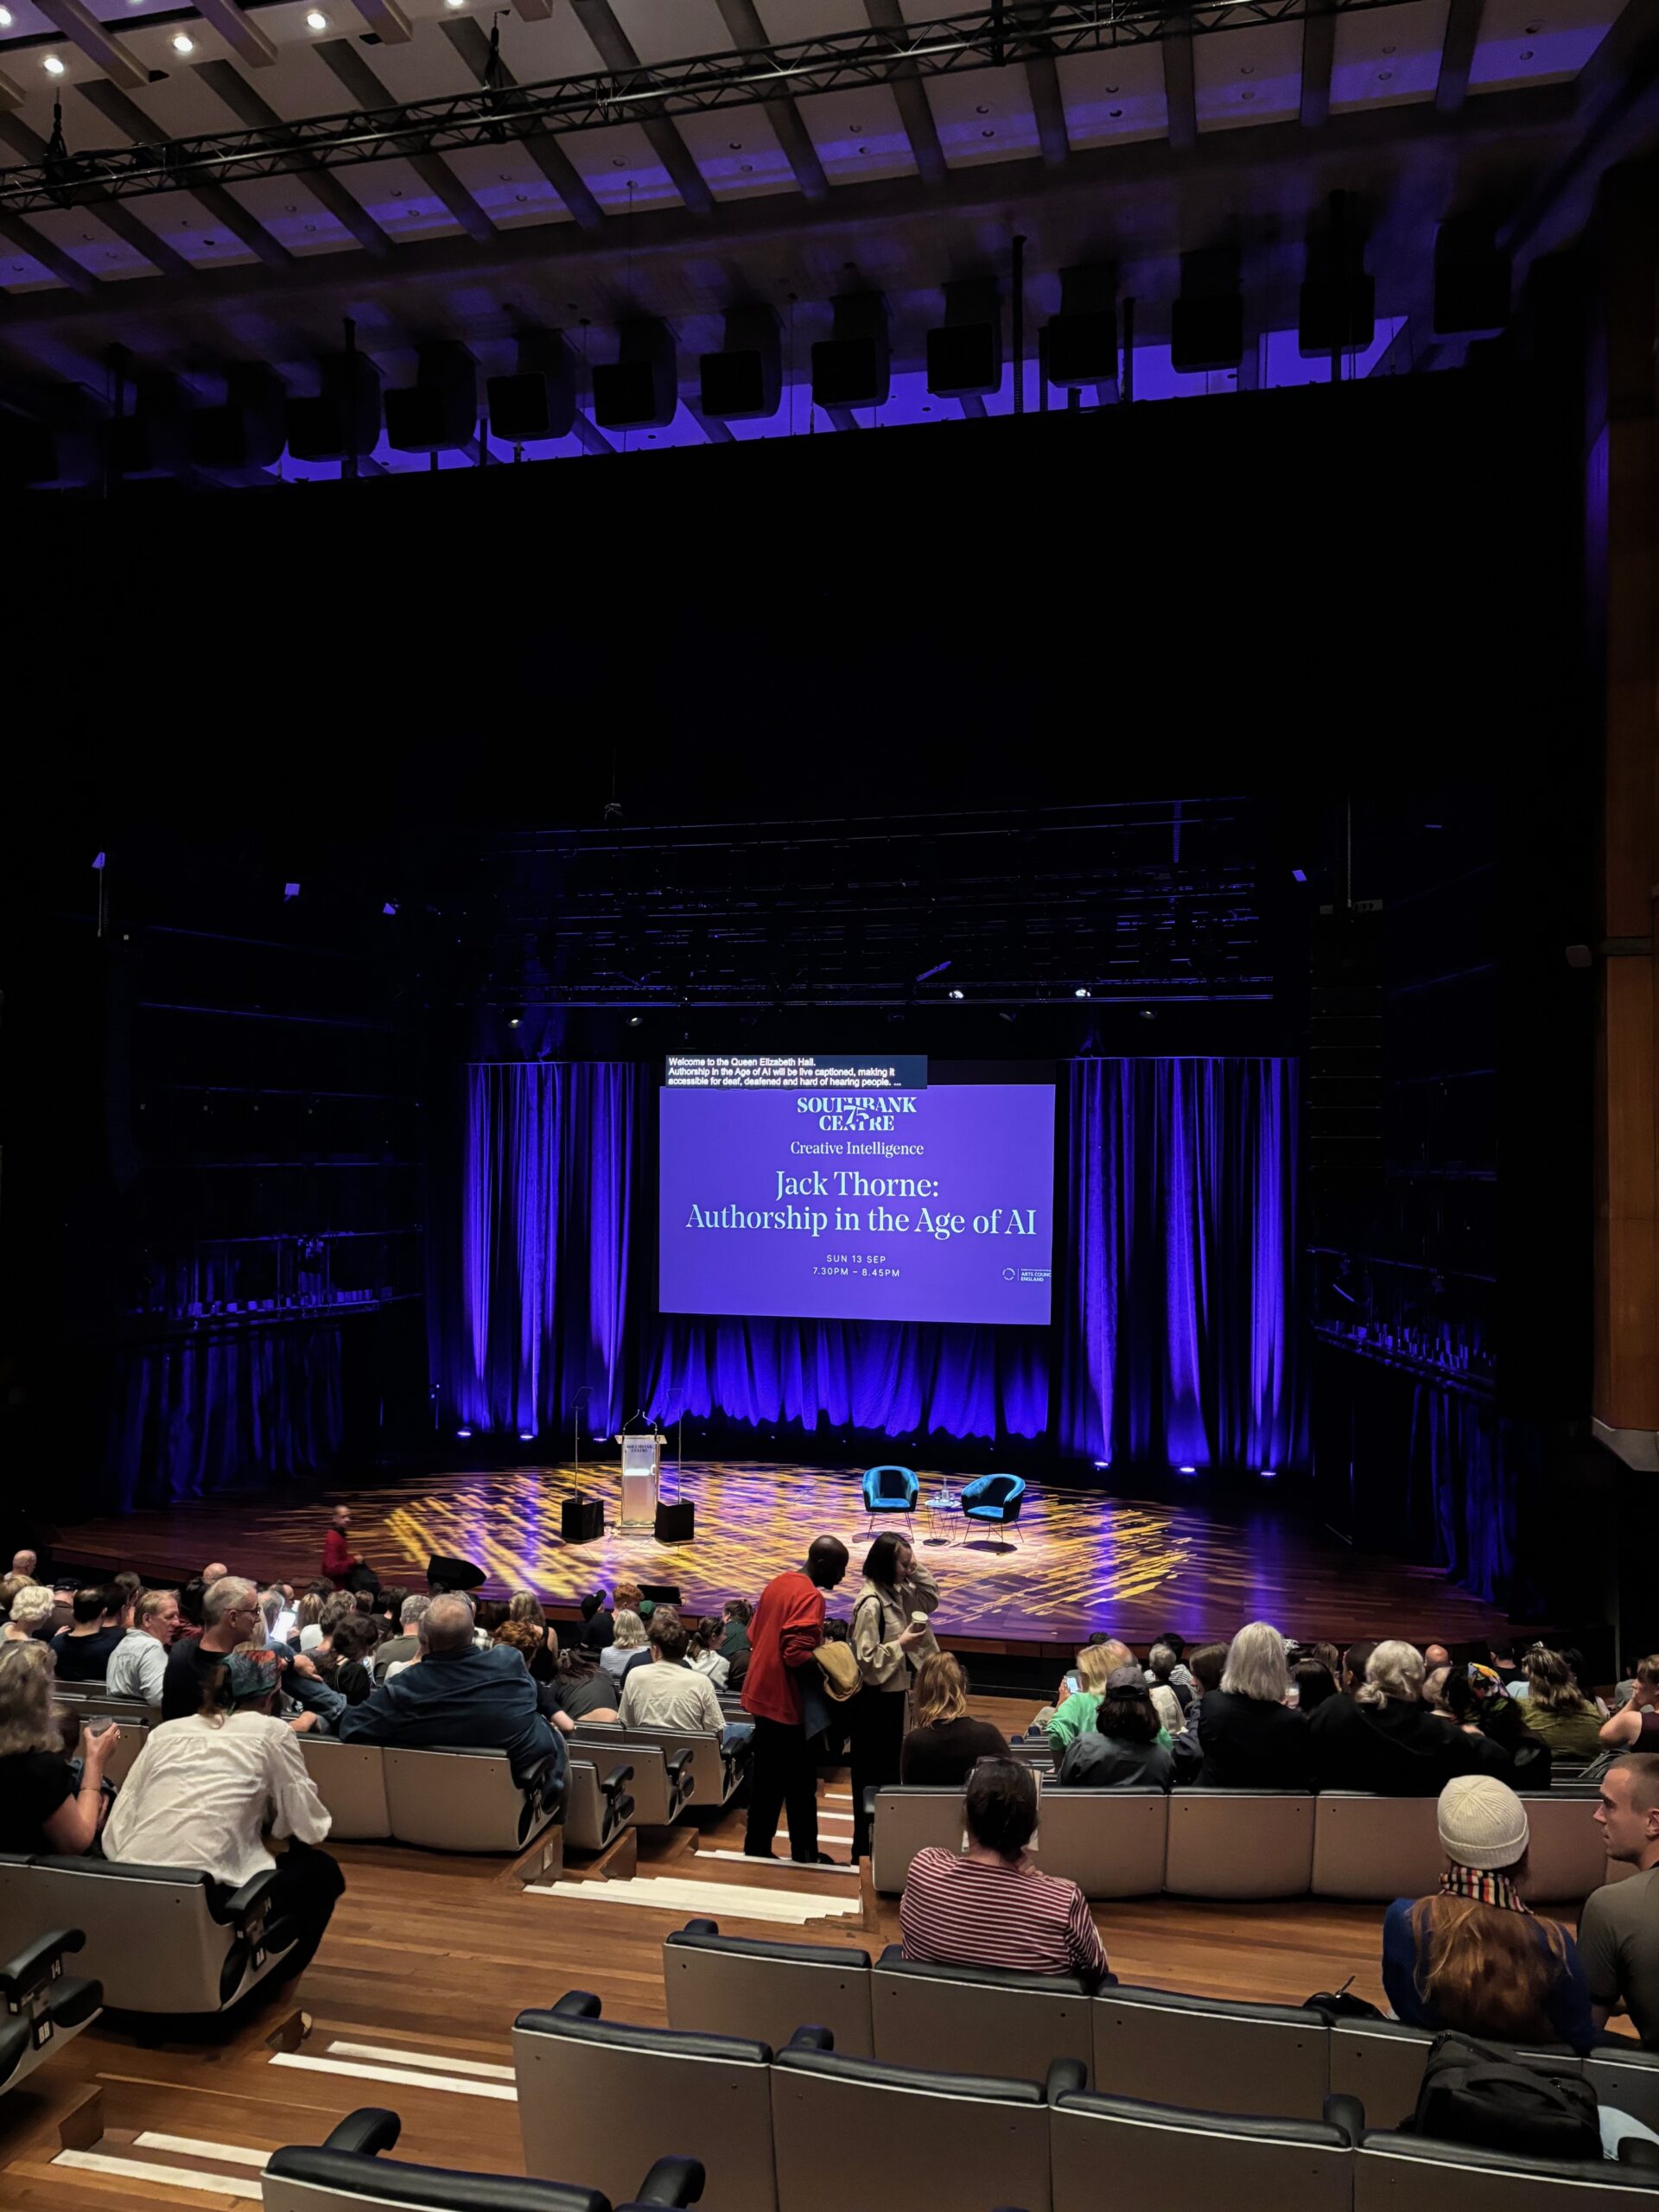
On a drizzly Sunday evening on London’s Southbank, I took my seat at the Queen Elizabeth Hall to watch a talk by Jack Thorne, renowned screen and stage writer and president of the Writers’ Guild, on authorship in the age of AI.
Tucked away from the rain, the plush seats, ambient purple lighting and warm wooden walls proved to be a juxtaposition to the thorny nature of the topic in discussion – and it could not have been more timely. Debate around rampant AI development and the need for urgent guardrails had exploded in the media in the days preceding the event.
But while that discourse centres on security and capability, this honed in on writing and copyright. As Thorne outlined at the start of his speech, how the government acts or doesn’t act over the next five years “will define what the next hundred years looks like for every writer in this country”. You could argue it will depend on a shorter timeframe than that.
It took me back to when I saw the play Disruption at the Park Theatre three years ago. What’s striking is how the same topics doing the rounds now were just as pertinent in my blog then: the tense relationship between fears and progress, how AI could “trigger a greater need for original human-made content” – an outcome we have already seen – and, most notably, the critical need for regulation.
Thorne’s speech centred on AI and writing in the creative industries. But it also raised salient points for authorship in tech PR. Two of the main ones were, one, how models are trained – i.e. what intellectual property they are using – and two, how they are used.
A breakdown of AI training
Thorne referenced the numerous copyright cases ongoing against tech firms, like the New York Times vs. OpenAI, to receive compensation for content allegedly used to train models (an essential step for preserving media). He also pointed to the news of big tech companies stripping and scanning secondhand books to train their models, and flagged how two of the three books named from one investigation were still in copyright.
To gain transparency, his first legislative solution was that AI companies should be obligated to declare what materials they use for training models. One idea was to include a percentage breakdown for any authors’ work used to generate an output – what input data contributed to the output data (e.g. 12% of X’s work, 20% of Y’s work). Immediately, this could provide fair payment where it’s needed.
This transparency would be beneficial for smaller tech companies and PRs too, allowing them to see what sources are used and ensure they aren’t unwittingly conducting AI-driven fraud, like what happened in the New York Times book review case. It’s an apt reminder for any tech leaders who wish to use AI to write articles: they could be plagiarising and stealing intellectual property. But the main guardrail against this lies in how it’s used.
The line for AI usage
The value of human content is not in question. What is in question is how AI impacts content creation and authenticity. Thorne drew a line between using AI for research, discussing ideas, formatting, “checking sense” and using it to generate content without declaring AI use. The line between using it as a supportive tool and using it as a writer in and of itself, when it pulls from other people’s work.
For PRs, this is most relevant when it comes to opinion pieces. With an article, there is an understanding that a reader is reading the opinion and words of the author of the piece. Of course, part of the work in PR is writing content for other people – but this is done with permission, the writer is collaborating with the author to express their views, and it’s compensated. That’s the difference.
Industry movements – and why they matter for tech PR
The industry direction and regulation around this topic serves as a warning against AI dependency for creative tasks. In particular, there’s been a recent push around identifying synthetic content through the SynthID technique, first developed by Google DeepMind.
Article 50 of the EU AI Act, as referenced by Thorne, obligates that AI providers must make synthetic content – audio, image, video, text – produced by their AI system as “detectable as artificially generated or manipulated”. Notably, this doesn’t apply to assistive functions for “standard editing” or input data that isn’t substantially altered.
This has led to a response by Anthropic to watermark text in future Claude models. This will be “undetectable” to a reader, but provides a way for organisations to check if text has likely been generated by Claude. Expect more of this to follow (SynthID is also in use by companies like OpenAI for images/audio), including in UK regulations.
As Thorne explained, this autumn, the findings from the UK’s AI labelling taskforce are set to be published, “which will apparently provide creators with clear technical tools to identify if their intellectual property has been used”. If anything, all of this should trigger tech PRs to consider how they use AI for content and the areas it should and shouldn’t be used for.
A seminal moment for content?
AI is delivering seismic scientific advances and organisational transformation. But this can’t be at the expense of copyright and human creativity. Thorne acknowledged a need to adapt, but there have to be guardrails in place.
There are many other points I can’t cover in this piece – the call for a Copyright Institute, AI impersonation of other authors, the shrinking of talent – and how this all impacts brand messaging, pathways for emerging PR professionals, their role as storytellers, etc.
It’s a complex topic, and it still feels like there’s a minefield of uncertainty and regulatory gaps. But it seems action on copyright and labelling AI text is building, and such moves will only accentuate the value of human PR teams and writers for tech companies.
Related Articles